

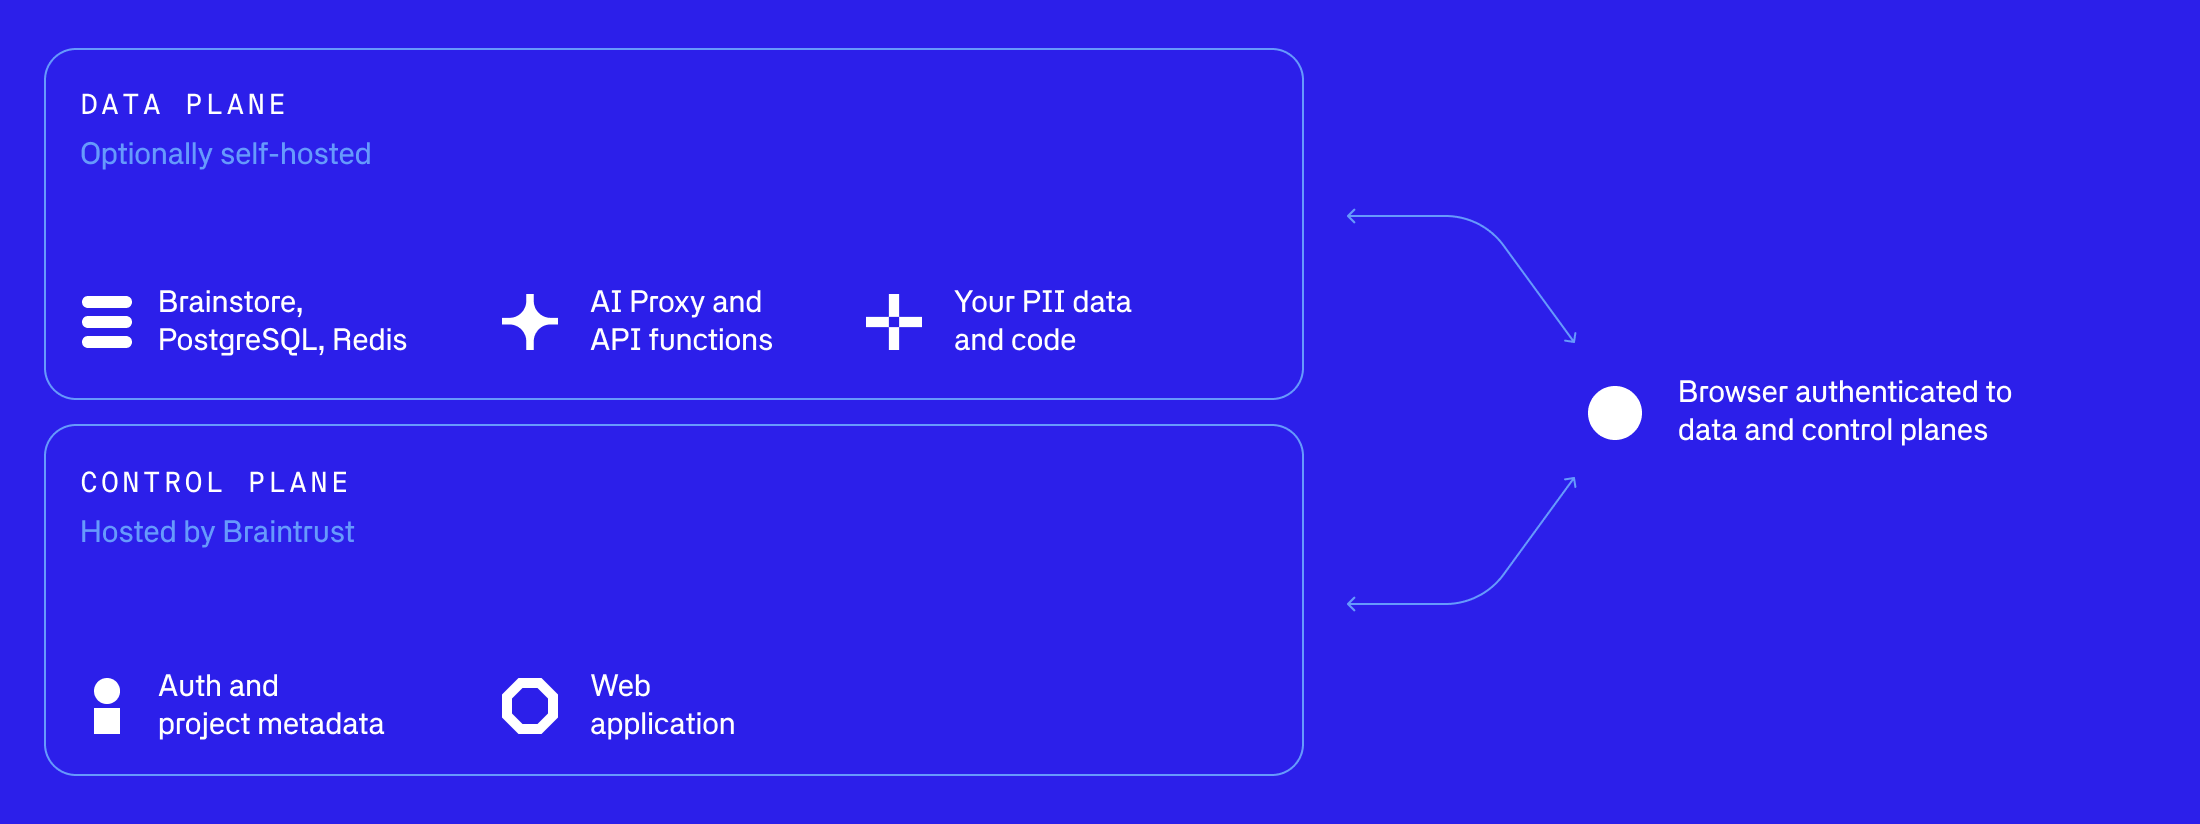
Control plane
The control plane manages the web UI, authentication, user management, and metadata storage (project names, experiment names, organization settings). It lives in Braintrust’s managed service and is delivered as SaaS. The control plane does not store or process your sensitive AI data. It communicates with your data plane only for authentication and metadata synchronization.Data plane
The data plane stores all sensitive AI data, including experiment logs, traces, spans, datasets, and prompt completions. When you use Braintrust’s SDKs, they send data directly to your data plane, not through the control plane. When you use the web UI, your browser communicates directly with your data plane via CORS.API service
The API service is the entry point for all SDK and browser requests to the data plane, built in TypeScript/Node.js.PostgreSQL
PostgreSQL stores metadata required to operate the platform, including pointers to raw data in object storage and aggregate statistics about the data. It is not the primary store for your AI data. Traces, spans, and logs live in Brainstore and object storage.Redis
Redis provides caching and coordination for session management, rate limiting, and Brainstore transaction ID assignment, which ensures consistent ordering of concurrent writes.Object storage
Object storage, such as Amazon S3 or Google Cloud Storage, is the durable, long-term home for all AI data. Brainstore writes every ingested span to object storage as a write-ahead log (WAL) entry and compacts those entries into indexed segments that also live on object storage. Because object storage is the source of truth, Brainstore nodes are stateless and can be replaced without data loss. See Trace data durability for ingestion guarantees and retry behavior.Brainstore
Brainstore is Braintrust’s high-performance database for ingesting and querying AI data. It uses object storage and a streaming Rust engine to load spans in real time, cutting down on latency and enabling fast full-text search over large volumes of trace data. Each customer’s data lives in its own partition, and Brainstore stores semi-structured fields natively rather than shredding them into columns, an approach that breaks down at the payload sizes AI traces produce. Brainstore runs as three distinct node types:- Writers ingest incoming spans and traces and write them to object storage.
- Readers serve ad-hoc queries, including those from the API and user-defined BTQL queries.
- Fast readers serve predictable UI queries, such as paginated viewers and span and trace lookups, in isolation from standard reader nodes, keeping the UI responsive while resource-intensive queries run on readers.
Write path
Every write appends to a WAL on object storage, allowing high throughput without coordination bottlenecks. In the background, two steps convert the WAL into a queryable index: Processing assigns records to time-ordered segments (ensuring all spans for a trace land together), and compacting converts those segments into efficient indexed formats including inverted indexes, row stores, column stores, and bloom filters. Indexing is asynchronous and continuous, so the system is always improving its read-optimized representation of the data.Read path
Brainstore runs an explicit query pipeline: Parsing SQL into an AST, binding names to schemas and fields, optimizing by pushing down filters and pruning unneeded fields early, then executing against the index to stream results. Full-text search across prompts and responses is a built-in query path. Reads don’t wait for compaction. When you query, Brainstore merges data from the WAL, processed-but-not-yet-compacted entries, and fully indexed segments, keeping queries real-time as background compaction proceeds.Braintrust Gateway
The data plane can run the Braintrust Gateway, which gives your applications a single OpenAI-compatible API to reach any LLM provider. When the data plane runs in your cloud account, LLM requests and cached completions stay on your infrastructure. Requests egress from your VPC directly to providers, and completions are cached in your Redis. Provider credentials follow the same split as other data: project-level provider secrets are stored in the data plane, and organization-level provider secrets are stored in the control plane.Where data is stored
Next steps
- Deployment options: Compare SaaS and BYOC.
- Bring your own cloud (BYOC): Run the data plane in your own cloud account.
- Security: Review how Braintrust protects your data.